Baar
For LLM agent builders: Baar enforces runtime cost limits before API calls execute, preventing runaway token spend and unexpected bills from agent loops.
Built by Orvi Das · Open Source · Free
In category: #99 of 169 · Open Source
Baar is a Community listing on Launch Llama with 8 total upvotes, founded by Orvi Das who joined in May 2026, compared against 5 alternatives.
Community listing
Listing status
8upvotes
Community score
Orvi Das (Joined May 2026)
Founder
Compared against 5 alternatives
Market comparison
Launched on Launch Llama May 11, 2026 · #16 of 26 that day
About
I left an agent loop running overnight. Woke up to a $47 bill — 20,000 GPT-4o tokens answering "what time is it?" queries.
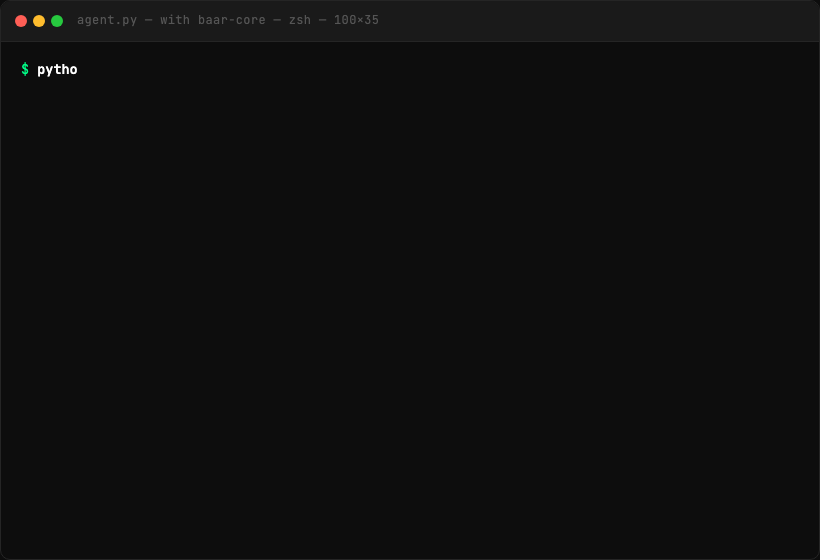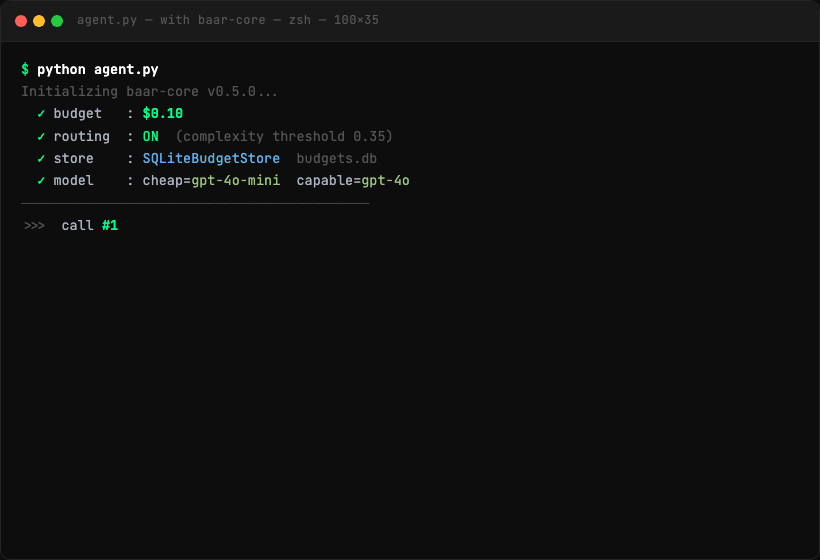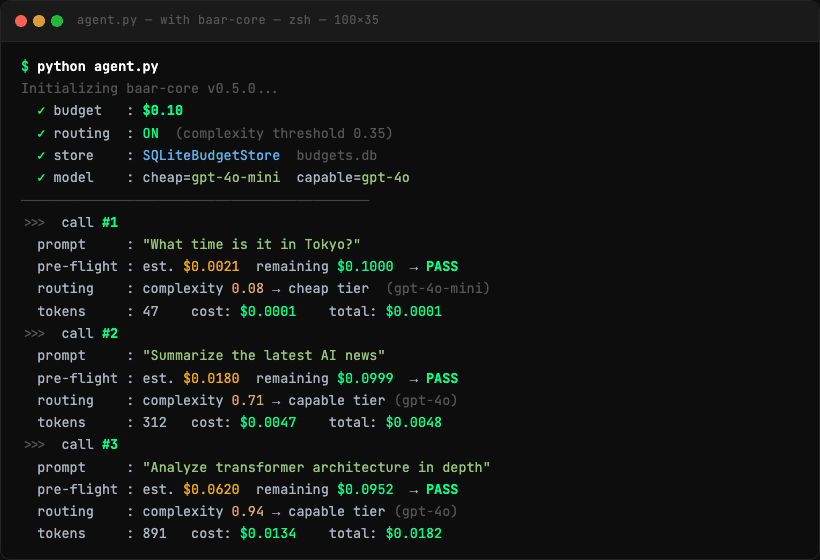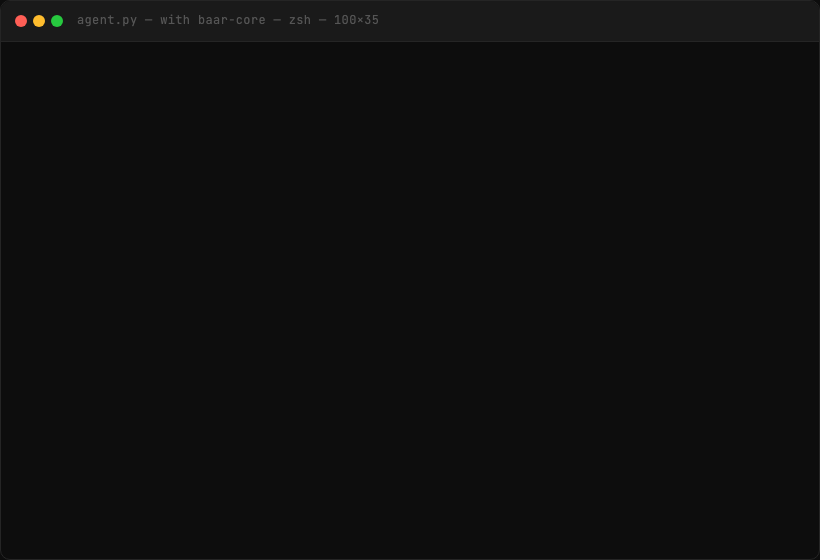
Baar-Core would have stopped it at $0.10. Before the first overage call. No network request made. $0 spent.
Key Features
- Proactive cost prevention by intercepting API calls before network requests are initiated
- Open-source core architecture for transparency and community-driven development
- Protection against runaway agent loops and repetitive automated queries
- Immediate local intervention to prevent unexpected billing overages
- Lightweight overhead designed to halt unnecessary LLM token consumption
Use Cases
- Set strict budget caps on autonomous AI agents to prevent expensive token loops during overnight runs
- Block repetitive or redundant LLM queries locally to avoid unnecessary API costs
- Filter low-value or "garbage" prompts before they reach your provider to save on billable tokens
- Protect your startup's burn rate by establishing a "firewall" that kills runaway network requests instantly
Who it is for
- Teams deploying autonomous agents in production
- SaaS founders giving users LLM access with per-user quotas
- Anyone who has had (or fears) a runaway agent bill
Pricing
Baar is free to use. See the website for details.
FAQ
What is baar-core?
baar-core is an open-source Python library that enforces hard budget limits on LLM agents. It intercepts API calls before they fire and blocks them locally when the budget is exhausted — no DNS lookup, no TCP connection, $0 charged.
How does baar-core prevent LLM overspending?
baar-core runs a pre-flight check before every LLM API call. It estimates the cost of the call and compares it against the remaining budget. If the estimated cost exceeds the budget, it raises a BudgetExhausted exception locally — before any network request is made — so you are never charged for the blocked call.
How do I install baar-core?
Install via pip: pip install baar-core. Requires Python 3.9 or higher.
Does baar-core support async agents?
Yes. baar-core is fully async-safe and thread-safe. It works with both sync and async LLM agent frameworks including LangChain, LlamaIndex, and custom asyncio agents.
What is semantic routing in baar-core?
Semantic routing automatically classifies each prompt by complexity and routes it to the cheapest model capable of handling it. Simple queries go to a cheap tier (e.g. gpt-4o-mini) and complex ones go to a capable tier (e.g. gpt-4o). This typically reduces LLM costs by 84–94% without any change to output quality.
Can baar-core enforce per-user budgets in a multi-tenant SaaS?
Yes. baar-core's SQLiteBudgetStore tracks spend per user_id across sessions. Budget state persists across restarts, is thread-safe and async-safe, and requires only 3 lines of code to set up.
Is baar-core free and open source?
Yes. baar-core is free and released under the MIT license. Source code is available at github.com/orvi2014/Baar-Core.
Alternatives
More in Open Source
New on Launch Llama
Launched this week · This month's launches · All products A–Z
In the news
Ask AI about Baar
Supporters
2 founders
2 founders supported Baar on Launch Llama.
For bots & AI agents
Machine-readable versions of Baar and Launch Llama. Fetch these instead of parsing this page.
This listing (.md) llms.txt llms-full.txt ai.txt Full catalog (.md) Endpoint index API docs MCP server MCP manifest Developer docs