ServiceLens
The mesh observed
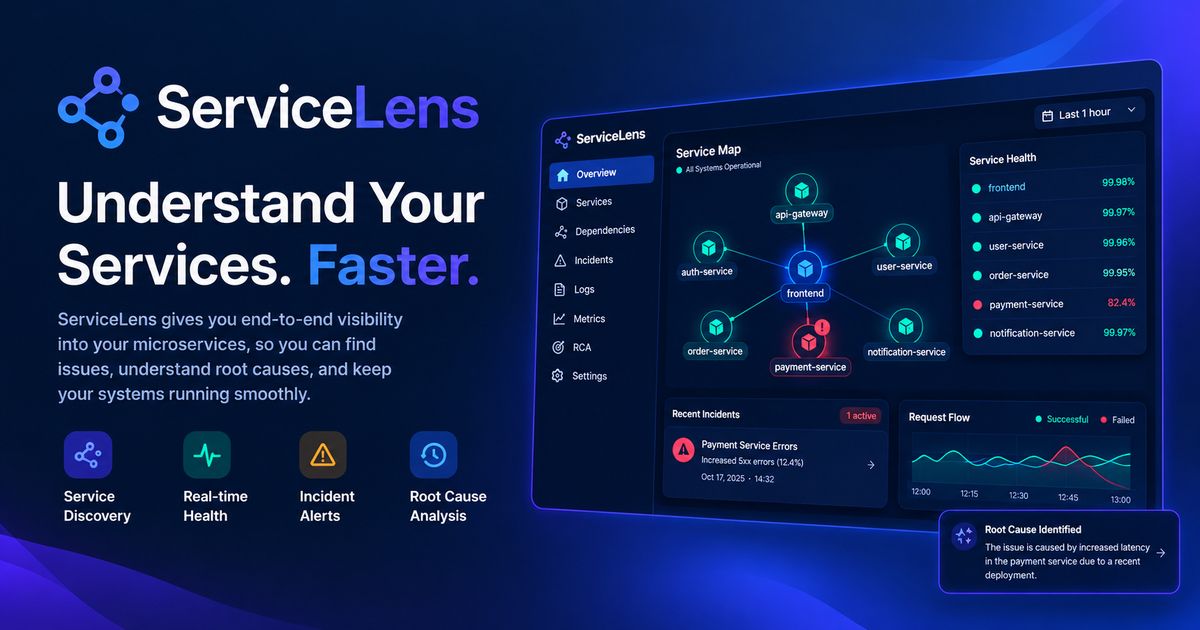
Helps platform and SRE teams onboard microservices from GitHub, monitor health checks, logs, and datastores, and get AI-assisted root-cause analysis with draft fix PRs during incidents.
Built by Abhishek Mallick · Artificial Intelligence · Developer Tools · Freemium
In category: #1970 of 1986 · Artificial Intelligence
ServiceLens is a Community listing on Launch Llama with 0 total upvotes, founded by Abhishek Mallick who joined in Oct 2026, compared against 6 alternatives.
Community listing
Listing status
0upvotes
Community score
Abhishek Mallick (Joined Oct 2026)
Founder
Compared against 6 alternatives
Market comparison
Launched on Launch Llama Oct 26, 2026 · #55 of 111 that day
About
Live demo: servicelens.buildlab.in
Search goes red at 3:07. The page says Search Service. Inventory stopped answering a few minutes earlier, and Search is just the one your users can see. You redraw who calls whom from env vars while someone is already asking for an update.
ServiceLens starts from the GitHub repos and draws that mesh itself. It checks each service, and when one fails it pages the person on your on-call sheet, writes the cause from the health, the neighbors, and the logs, and opens a draft fix PR. The on-call engineer does not need an account. The email link is enough, and if nobody acknowledges, it escalates. When the service comes back, the incident closes and leaves a short note, so the next one is not a blank page.
A service can register itself from CI, so the graph does not go stale the week after you set it up. After a deploy it calls the GET routes in the code and fails the run if production is not serving them.
Reads each repo at a pinned commit and maps routes plus the env vars services use to call each other. Edges it is not sure about stay dashed until you confirm them.
Health checks every minute over HTTP, TCP, Postgres, and Redis. Services it cannot reach send a heartbeat.
Rules for down, slow, and error-heavy. One bad check does not page anyone, and a service only has one open incident.
On-call from a sheet, then email and Slack, with acknowledge, escalation, quiet hours, and per-person severity.
Log ingest, search, and a live tail. Warnings and errors from the open stay on the incident.
A write-up from the last half hour of health, neighbor status, those logs, failed checks, and how the last similar incident on that service was closed.
A draft fix PR from the real source files. It does not merge, one PR per repo per hour, and it stops if the file changed underneath it.
Contract checks on the GET routes found in the code, by hand, on a schedule, or from CI.
Drills that take a service down so you can watch the page, the write-up, and the notifications fire.
A live graph, an in-app feed, owner / editor / viewer roles, and an audit log.
An API and SKILL.md so CI or an agent can onboard the mesh.
Key Features
- Delivers maps downstream calls, endpoints, and events from GitHub repos automatically
- Delivers renders a live service topology that flags ambiguous edges
- Tracks uptime probes, p95 latency, error rates, and logs for each service
- Delivers traces requests across services and shows env var wiring between them
- Drafts AI root-cause analysis and fix PRs for production incidents
Use Cases
- Onboarding microservices from GitHub repos and mapping their dependencies and topology automatically
- Investigating production incidents with AI-assisted root-cause analysis and generating draft fix PRs
- Monitoring health checks, logs, and datastores across services to spot degraded or down components
Who it is for
- Platform engineering teams running microservice architectures
- SRE teams responsible for production uptime and incident response
- Backend developers who need visibility into service dependencies and failures
Pricing
Free plan, Pro(29$p.m), Enterprise Support
Alternatives
 PulseCareFor engineering teams: PulseCare monitors uptime, Web Vitals, and deploy regressions then explains what changed so you fix performance issues first.
 NovixFor development teams: Novix analyzes bug reports, tests fixes in sandbox, and opens pull requests so you approve patches without manual work.
Ask AI about ServiceLens